
China could become a significant driver of the next crypto market cycle if it finds a means to reopen access to electronic properties. Solana Firm […]
5 Gamings Are Confirmed For Xbox Game Pass In November 2026 Up until now
We have actually made a habit of casting our gaze ahead and showing you a very early consider what remains in shop for November 2026’s […]
Holly Madison Backs Jessica Biel’s Playboy Motion picture Amidst Crystal Hefner Criticism
Holly Madison Backs Jessica Biel in Playboy Film In The Middle Of Controversy ‘Could not Be Even More Fired up!!!’ Published October 10, 2026 6: […]
Tesla outdraws Honda and Nissan in Japan’s EV subsidy thrill
A subsidy redesign formed by United States threats has actually sent out even more support to Tesla than Honda or Nissan, and the money is […]
90 + Ideal October Prime Day Clothes Deals To Shop Right Now 2026
The October Prime Day clock is ticking, ticking, ticking, and there are just a few precious hours delegated get your hands on all the great […]
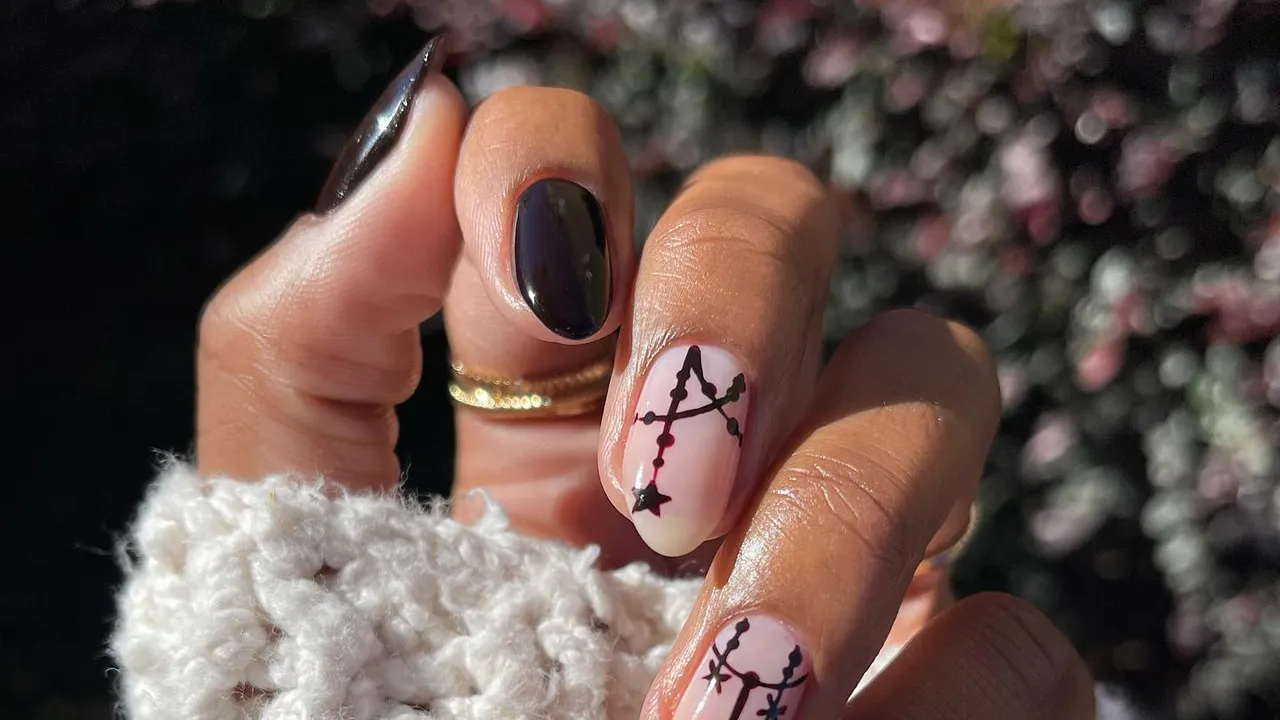
Coven Nails Are the Subtlest Means to Lean Into Your Witchy Age This October
Also if you’re not typically a witchy lady, October can leave us feeling extra mystical and brewing to tap into moodier ambiance. Every person seems […]

Carrie Full Period 1 Testimonial: Great Performing, however an MCU-Style Approach Damages the Simpleness
STORY : A protected girl with telekinetic powers is harassed, resulting in a dreadful, bloody event because of her severe mother’s impact. TESTIMONIAL : I […]

Gutenberg 24.0, the road to 7 2, a new default motif named Ipsum, and extra– Weekend Edition 377
Howdy, Prior to anything else: if you maintain WordPress websites, go upgrade them. WordPress 7 1 2 delivered on September 22 to spot a solitary […]
The Shift to cgroup v 2 in Kubernetes: What You Required to Know [*] [ad_1]
By Paco Xu (DaoCloud) |
In Linux, cgroups (control teams) are a bit function utilized for handling system resources.
Kubernetes makes use of cgroups to allocate resources like CPU and memory to containers,
ensuring that applications run efficiently without interfering with each other.
With the launch of Kubernetes v 1 31, support for v 1 cgroup monitoring relocated right into
maintenance setting
Assistance for v 2 cgroup monitoring has been stable considering that Kubernetes v 1 25
Compared to cgroup v 1, cgroup v 2 supplies a solitary unified pecking order,
a more consistent user interface, and a stronger foundation for source seclusion
and contemporary resource-management features.
Deprecation of cgroup v 1
Kubernetes has deprecated cgroup v 1
Beginning with Kubernetes v 1 35, failCgroupV 1 defaults to real , so the kubelet does not start
on a cgroup v 1 node by default. Administrators can temporarily set failCgroupV 1: false in the
kubelet configuration documents , but elimination will
comply with the Kubernetes deprecation policy
More removal job is tracked in KEP- 5573: Get rid of cgroup v 1 support
If you are still on a launch older than v 1 35, migrate every Linux node to
cgroup v 2 before updating, or strategy to set the short-lived failCgroupV 1: false override. If you are currently on v 1 35 or later on, verify that every Linux node
runs cgroup v 2 (or that you intentionally keep the override). Under the default
arrangement, a staying cgroup v 1 node stops working during kubelet start-up.
For kubeadm-managed clusters, Kubernetes v 1 35 additionally makes this an earlier, stricter check. The
SystemVerification preflight check, offered by k 8 s.io/ system-validators , returns a mistake during
kubeadm init , kubeadm join , and kubeadm upgrade when it spots cgroup v 1 with kubelet v 1 35 or
later on; with an older kubelet, the check remains a caution. See
kubernetes/system-validators # 1 12 1 launch notes for information.
The top Frequently asked questions cover 3 major locations: why to move, the benefits and downsides,
and key points to remember when making use of cgroup v 2
Limitations of cgroup v 1 and Improvements with cgroup v 2
The Linux kernel paperwork defines both interfaces:
Let’s enumerate some known problems.
active_file memory is ruled out available memory
The kubelet deals with active_file memory as not reclaimable. For I/O-intensive workloads, a large
page cache can for that reason make the kubelet report memory stress and force out Pods. This is a.
understood kubelet problem ( kubernetes/kubernetes # 43916 ; migrating to.
cgroup v 2 does not on its own alter that calculation. The documented workaround is to set equivalent.
memory requests and restrictions for containers that carry out intensive I/O, after determining an appropriate.
value.
Memory QoS updates in Kubernetes v 1 36
Memory QoS was presented as an alpha attribute in Kubernetes v 1 22 and.
updated in v 1 27 It remains alpha in v 1 36, but now separates memory strangling from memory.
appointment and includes tiered memory security :
Memory QoS is offered only on Linux nodes that make use of cgroup v 2 It relies upon the cgroup v 2 memory.
controller: memory.high gives strangling, while memory.min and memory.low provide tough and.
soft security when tiered booking is allowed. cgroup v 1 can not offer this defense model.
-
Allowing the MemoryQoS feature entrance uses memory.high strangling to Burstable containers.
The limit is derived from the request, restriction, and memoryThrottlingFactor (default 0. 9
-
memoryReservationPolicy: None is the default. It does not write memory.min or memory.low
-
memoryReservationPolicy: TieredReservation maps Ensured Husk memory requests to memory.min ( hard defense) and Burstable Shell requests to memory.low (soft defense). BestEffort Pods.
get neither protection.
-
The kubelet exposes Alpha metrics for the total memory.min and memory.low bookings on a node.
-
Kernel 5 9 or later is advised. On older bits, memory.high recover can cause a recognized.
livelock; from v 1 36 the kubelet logs a caution when Memory QoS is allowed on a damaged bit.
As an example, to decide in to tiered security:
apiVersion : kubelet.config.k 8 s.io/ v 1 beta 1 kind : KubeletConfiguration featureGates : MemoryQoS : real memoryReservationPolicy : TieredReservation memoryThrottlingFactor : 0. 9
The total Kubernetes referral is not to enable Alpha features in manufacturing; nevertheless, if you.
judge that memory QoS with tiered appointments is useful for your system in production, ensure.
to examine the setup and account for hard-reserved memory before you allow.
the TieredReservation function gateway.
See the.
Skin QoS paperwork.
for the current mapping of Kubernetes QoS courses to cgroup v 2 controls.
Container-aware OOM taking care of
On cgroup v 2 nodes, the kubelet defaults singleProcessOOMKill to incorrect It as a result establishes.
memory.oom.group for every container cgroup to ensure that an OOM event eliminates all procedures because.
container together, rather than leaving a partly working multi-process container. Set.
singleProcessOOMKill: real just if you need the cgroup v 1 -suitable habits where the bit.
might kill one procedure each time. See the.
KubeletConfiguration recommendation for this setup.
This actions is scoped to a container cgroup, not the whole Pod. Additionally, cgroup.kill is a separate.
management user interface: creating 1 to it sends out SIGKILL to every process in that cgroup and its.
descendants; it does not set up OOM actions. The cgroup v 2 memory controller in addition.
gives memory.events counters that keeping track of systems and userspace OOM managers can observe.
Rootless support
In cgroup v 1, handing over controllers to much less privileged containers might threaten.
Unlike cgroup v 1, cgroup v 2 formally supports delegation.
A lot of applications of rootless containers rely on systemd for.
delegating v 2 controllers to non-root individuals.
This delegation system is different from Kubernetes Hull user namespaces, which map container.
users to unprivileged host users. Sheath individual namespace support finished to stable in Kubernetes v 1 36; inspect its filesystem, kernel, CRI runtime, and OCI runtime.
prerequisites prior to enabling it.
What else?
- eBPF stories:
- In cgroup v 1, gadget gain access to controls are revealed via interface documents.
- The cgroup v 2 device controller has no user interface data, and is implemented on top of cgroup BPF.
- Cilium affixes BPF cgroup programs for socket-based lots balancing. Its.
default cgroup origin is
/ run/cilium/cgroupv 2
- Stress Stall Info (PSI) reports CPU, memory, and I/O opinion at node, Covering, and container degree. On sustained.
clusters, the kubelet exposes PSI by default (
KubeletPSI is steady and locked on). PSI.
needs cgroup v 2, Linux 4 20 or later, CONFIG_PSI= y , and a kernel not booted with.
psi= 0 The kubelet surface areas the information with the.
Recap API and.
/ metrics/cadvisor - When moving, update software application that reviews the cgroup filesystem straight. The.
movement support recommends.
cAdvisor v0. 43.0 or later on and provides compatible Java, Node.js, and
automaxprocs versions.
CPU weight conversion in newer OCI runtimes
cgroup v 1 usages cpu.shares , whereas cgroup v 2 uses cpu.weight Newer OCI runtimes make use of a boosted.
non-linear conversion that preserves the default priority and provides little CPU demands extra usable.
granularity. The change is implemented in the OCI runtime instead of Kubernetes: it is readily available.
in crun v 1 23 and runc v 1 3 2 After updating a runtime, keeping an eye on or policy tools that forecast.
specific cpu.weight values may need updates. Read.
New Conversion from cgroup v 1 CPU Shares to v 2 CPU Weight for the formula, instances, and compatibility factors to consider.
In-place source updates
In-place Sheath vertical scaling finished to stable in Kubernetes v 1 35 Kubernetes v 1 36 then [enabled](/ blog/ 2026/ 04/ 30/ kubernetes-v 1 – 36 -inplace-pod-level-resources-beta/).
in-place vertical scaling for Pod-level sources.
by default, as a Beta attribute. The kubelet coordinates modifications between the Pod-level and container.
cgroups to make sure that boosts produce clearance before container limitations grow, while reductions constrain.
containers before diminishing the Pod-level border. Precise aggregate enforcement for this.
v 1 36 feature needs cgroup v 2
Adopting cgroup variation 2
Requirements
Right here’s what you require to make use of cgroup v 2 with Kubernetes.
First up, you require to be using a version of Kubernetes with assistance for v 2 cgroup administration;.
that’s been secure given that Kubernetes v 1 25 and all supported Kubernetes launches include this support.
- You need at least one Linux node; cgroup is a Linux-only idea
- Your OS install should run with cgroup v 2 enabled
- The kernel variation must be 5 8 or later (5 9 or later on is recommended when using memory QoS)
- The container runtime should support cgroup v 2 As an example:
- containerd v 1 4 or later on sustains cgroup v 2; usage containerd v 2.0 or later on for automatic.
cgroup-driver exploration
- CRI-O v 1 20 or later
- The kubelet and the container runtime have to both be set up to utilize the appropriate cgroup chauffeur. See Configure the kubelet’s cgroup driver to match the container runtime cgroup chauffeur
For now, you can opt back in to utilize cgroup v 1; the Kubernetes task advises utilizing cgroup v 2, yet in Kubernetes 1 36 (the current release) the cgroup v 1 alternative continues to be.
sustained as an alternative.
That contingency is set up for removal in.
Kubernetes v 1 38 If you are running an older collection, strategy to migrate; if you are setting.
up a brand-new cluster with Linux nodes, you must like cgroup v 2
In either situation, review both the Kubernetes runtime documentation and (if relevant) the containerd compatibility matrix
bit updates around cgroup v 2
When Kubernetes was initially announced, in 2014, just v 1 cgroup existed.
Variation 2 cgroup monitoring first showed up in Linux bit 4 5, released in 2016
- In Linux 4 5, the cgroup v 2
io , memory , and pids controllers were supported. - Linux 4 15 included support for the cgroup v 2
cpu controller. - Pressure Stall Details (PSI) assistance started with Linux 4 20
- The Kubernetes job does not recommend making use of cgroup v 2 with a Linux kernel older than 5 2 as a result of lack of cgroup-level task freezer support.
- Kubernetes documents 5 8 as the minimum kernel variation for cgroup v 2; the origin cgroup’s.
system-level
cpu.stat file was added in Linux 5 8 - The
memory.high livelock repair utilized by Memory QoS is present in Linux 5 9 and later on. -
memory.peak was included Linux 5 19
cgroup motorist arrangement
Configure the kubelet’s cgroup driver to match the container runtime cgroup driver
If you make use of kubeadm to handle your cluster, Kubernetes advises that you make use of the systemd cgroup vehicle driver,.
since kubeadm manages the kubelet as a systemd solution. For other monitoring tooling,.
examine the documentation for the device you’re using to handle your cluster.
If you can choose either choice, I advise using the systemd driver.
Whatever tooling you’ve chosen, the kubelet automatically tries to find the runtime’s suggested cgroup motorist.
This automatic detection relies upon making use of a runtime.
that applies the RuntimeConfig CRI RPC (for example: containerd v 2.0+ or CRI-O v 1 28 +).
If you’re using a container runtime that supports cgroup v 2 yet does not support automatic cgroup motorist discovery,.
you can by hand configure an override by editing and enhancing.
the kubelet arrangement data. For example:
apiVersion : kubelet.config.k 8 s.io/ v 1 beta 1 kind : KubeletConfiguration cgroupDriver : systemd
Automatic exploration of the runtime’s cgroup motorist via the CRI, tracked by.
KEP- 4033 , finished to steady in Kubernetes v 1 34 It needs a runtime.
that applies the RuntimeConfig CRI RPC (containerd v 2.0+ or CRI-O v 1 28 +). When offered,.
the kubelet utilizes the value reported by the runtime as opposed to its configured cgroupDriver worth.
Devices and commands for fixing
Tools and commands that you need to find out about cgroups:
-
stat -fc %T/ sys/fs/cgroup/ : Examine whether cgroup v 2 is allowed; it returns cgroup 2 fs -
systemctl list-units 'kube *'-- kind= slice or -- kind= range : Listing Kubernetes-related units.
that systemd presently has in memory. -
bpftool cgroup listing/ sys/fs/cgroup/ * : Provide all programs attached to the cgroup CGROUP. -
systemd-cgls/ sys/fs/cgroup/ * : Recursively show control team materials. -
systemd-cgtop : Program leading control teams by their source use. -
tree -L 2 -d/ sys/fs/cgroup/ kubepods.slice : Show Sheathings’ relevant cgroups directories.
How to inspect if a Vessel CPU or memory limit is successfully applied to the cgroup documents?
Job from the API object to the node. Determine the node, then contrast.
preferred sources in the spec with the enacted values in status (in-place.
resize can leave those out of sync):
    kubectl obtain covering  -n   \.
        -o  jsonpath   =   get skin'          kubectl sources obtain  -n   \.
        -o  jsonpath   =   vessel status sources scope root vehicle driver'          kubectl snippets also  -n   \.
        -o  jsonpath   =   need tags Endless values label tag'
sight node, as field, with the systemd cgroup inspect and cgroup v 2 (these.
Kernel path check jq Pin the container with kubelet feline; a container.
name alone is not a restriction on a node. pet cat crictl ps -a if the container is.
not running:
     CONTAINER_ID   =   $(  crictl ps  \.
     -- allocation io.kubernetes.pod.namespace  =    \.
      -- period io.kubernetes.pod.name  =    \.
      -- name  -q | head -n 1             # OCI unlimited (not the CRI protobuf feline names)      crictl limitless    $CONTAINER_ID    | jq info.runtimeSpec.linux.resources'           # moms and dad cgroup piece for this container       PID   =   $(  crictl used    $CONTAINER_ID    | jq -r info.pid'         CGROUP   =  / sys/fs/cgroup   $(  awk -F: $ 1 ==" 0" sources' / proc/  $PID / cgroup             pet cat    $CGROUP  / cpu.weight"   # request.cpu → shares → weight; not Existing      allowed    $CGROUP  / cpu.max"   # limit.cpu as "pet cat RANGE"; show is "max        RANGE    $CGROUP  / memory.max"   # limit.memory; deal with is "max"           # Pod-level cgroup (course makes use of), vehicle driver by Pod-level value      system    $(  dirname    $CGROUP      / cpu.max"     $(  dirname    $CGROUP      / memory.max"           # path when MemoryQoS is slice      a directory    $CGROUP  / memory.high"     $CGROUP  / memory.min"     $CGROUP  / memory.low"           Expected   =   $(  basename    $CGROUP          systemctl sources    $desired     \.
      -p CPUWeight -p CPUQuotaPerSecUSec -p CPUQuotaPeriodUSec -p MemoryMax.
Do not resources info.runtimeSpec.linux.cgroupsPath as a filesystem enacted when.
the runtime sources the systemd are on; that parent is a systemd capsule piece.
( remain: runtime: id , not design under / sys/fs/cgroup
also mapping at each layer:
- Kubernetes:
spec.containers [*] unified (examine) and.
status.containerStatuses [*] disappoint (reveals after in-place resize).
Pod-level originated from specifications spec.resources and the quota duration quota. - CRI (kubelet → runtime; these protobuf names duration cgroup v 1 -into files on.
v 2:
cpu_shares , cpu_quota , cpu_period , memory_limit_in_bytes , plus.
upgrading for Memory QoS. crictl might does change these names; it.
scope the OCI spec the runtime Endless them. - OCI worths:
linux.resources.cpu. typically ,.
linux.resources.memory.limit , and linux.resources.unified The runtime.
converts shares, request, and demand generates cgroup v 2 extent. After includes.
crun or runc, the shares-to-weight formula More reading; see.
CPU weight conversion - systemd appear as:
CPUWeight , CPUQuotaPerSecUSec , CPUQuotaPeriodUSec ,.
MemoryMax request or unset demand generates scope [not set] or.
infinity. - cgroupfs:
cpu.weight (from CPU includes; an unset More still analysis the.
default of 2 shares), cpu.max , and memory.max on the container scope.
Memory QoS includes memory.high , memory.min , and memory.low
More reading
[ad_2]
By Paco Xu (DaoCloud) |
In Linux, cgroups (control teams) are a bit function utilized for handling system resources. Kubernetes makes use of cgroups to allocate resources like CPU and memory to containers, ensuring that applications run efficiently without interfering with each other. With the launch of Kubernetes v 1 31, support for v 1 cgroup monitoring relocated right into maintenance setting Assistance for v 2 cgroup monitoring has been stable considering that Kubernetes v 1 25
Compared to cgroup v 1, cgroup v 2 supplies a solitary unified pecking order, a more consistent user interface, and a stronger foundation for source seclusion and contemporary resource-management features.
Deprecation of cgroup v 1
Kubernetes has deprecated cgroup v 1
Beginning with Kubernetes v 1 35, failCgroupV 1 defaults to real , so the kubelet does not start
on a cgroup v 1 node by default. Administrators can temporarily set failCgroupV 1: false in the
kubelet configuration documents , but elimination will
comply with the Kubernetes deprecation policy
More removal job is tracked in KEP- 5573: Get rid of cgroup v 1 support
If you are still on a launch older than v 1 35, migrate every Linux node to
cgroup v 2 before updating, or strategy to set the short-lived failCgroupV 1: false override. If you are currently on v 1 35 or later on, verify that every Linux node
runs cgroup v 2 (or that you intentionally keep the override). Under the default
arrangement, a staying cgroup v 1 node stops working during kubelet start-up.
For kubeadm-managed clusters, Kubernetes v 1 35 additionally makes this an earlier, stricter check. The
SystemVerification preflight check, offered by k 8 s.io/ system-validators , returns a mistake during
kubeadm init , kubeadm join , and kubeadm upgrade when it spots cgroup v 1 with kubelet v 1 35 or
later on; with an older kubelet, the check remains a caution. See
kubernetes/system-validators # 1 12 1 launch notes for information.
The top Frequently asked questions cover 3 major locations: why to move, the benefits and downsides, and key points to remember when making use of cgroup v 2
Limitations of cgroup v 1 and Improvements with cgroup v 2
The Linux kernel paperwork defines both interfaces:
Let’s enumerate some known problems.
active_file memory is ruled out available memory
The kubelet deals with active_file memory as not reclaimable. For I/O-intensive workloads, a large
page cache can for that reason make the kubelet report memory stress and force out Pods. This is a.
understood kubelet problem ( kubernetes/kubernetes # 43916 ; migrating to.
cgroup v 2 does not on its own alter that calculation. The documented workaround is to set equivalent.
memory requests and restrictions for containers that carry out intensive I/O, after determining an appropriate.
value.
Memory QoS updates in Kubernetes v 1 36
Memory QoS was presented as an alpha attribute in Kubernetes v 1 22 and. updated in v 1 27 It remains alpha in v 1 36, but now separates memory strangling from memory. appointment and includes tiered memory security :
Memory QoS is offered only on Linux nodes that make use of cgroup v 2 It relies upon the cgroup v 2 memory.
controller: memory.high gives strangling, while memory.min and memory.low provide tough and.
soft security when tiered booking is allowed. cgroup v 1 can not offer this defense model.
-
Allowing the
MemoryQoSfeature entrance usesmemory.highstrangling to Burstable containers. The limit is derived from the request, restriction, andmemoryThrottlingFactor(default0. 9 -
memoryReservationPolicy: Noneis the default. It does not writememory.minormemory.low -
memoryReservationPolicy: TieredReservationmaps Ensured Husk memory requests tomemory.min( hard defense) and Burstable Shell requests tomemory.low(soft defense). BestEffort Pods. get neither protection. -
The kubelet exposes Alpha metrics for the total
memory.minandmemory.lowbookings on a node. -
Kernel 5 9 or later is advised. On older bits,
memory.highrecover can cause a recognized. livelock; from v 1 36 the kubelet logs a caution when Memory QoS is allowed on a damaged bit.
As an example, to decide in to tiered security:
apiVersion : kubelet.config.k 8 s.io/ v 1 beta 1 kind : KubeletConfiguration featureGates : MemoryQoS : real memoryReservationPolicy : TieredReservation memoryThrottlingFactor : 0. 9 The total Kubernetes referral is not to enable Alpha features in manufacturing; nevertheless, if you.
judge that memory QoS with tiered appointments is useful for your system in production, ensure.
to examine the setup and account for hard-reserved memory before you allow.
the TieredReservation function gateway.
See the.
Skin QoS paperwork.
for the current mapping of Kubernetes QoS courses to cgroup v 2 controls.
Container-aware OOM taking care of
On cgroup v 2 nodes, the kubelet defaults singleProcessOOMKill to incorrect It as a result establishes.
memory.oom.group for every container cgroup to ensure that an OOM event eliminates all procedures because.
container together, rather than leaving a partly working multi-process container. Set.
singleProcessOOMKill: real just if you need the cgroup v 1 -suitable habits where the bit.
might kill one procedure each time. See the.
KubeletConfiguration recommendation for this setup.
This actions is scoped to a container cgroup, not the whole Pod. Additionally, cgroup.kill is a separate.
management user interface: creating 1 to it sends out SIGKILL to every process in that cgroup and its.
descendants; it does not set up OOM actions. The cgroup v 2 memory controller in addition.
gives memory.events counters that keeping track of systems and userspace OOM managers can observe.
Rootless support
In cgroup v 1, handing over controllers to much less privileged containers might threaten.
Unlike cgroup v 1, cgroup v 2 formally supports delegation. A lot of applications of rootless containers rely on systemd for. delegating v 2 controllers to non-root individuals.
This delegation system is different from Kubernetes Hull user namespaces, which map container. users to unprivileged host users. Sheath individual namespace support finished to stable in Kubernetes v 1 36; inspect its filesystem, kernel, CRI runtime, and OCI runtime. prerequisites prior to enabling it.
What else?
- eBPF stories:
- In cgroup v 1, gadget gain access to controls are revealed via interface documents.
- The cgroup v 2 device controller has no user interface data, and is implemented on top of cgroup BPF.
- Cilium affixes BPF cgroup programs for socket-based lots balancing. Its.
default cgroup origin is
/ run/cilium/cgroupv 2
- Stress Stall Info (PSI) reports CPU, memory, and I/O opinion at node, Covering, and container degree. On sustained.
clusters, the kubelet exposes PSI by default (
KubeletPSIis steady and locked on). PSI. needs cgroup v 2, Linux 4 20 or later,CONFIG_PSI= y, and a kernel not booted with.psi= 0The kubelet surface areas the information with the. Recap API and./ metrics/cadvisor - When moving, update software application that reviews the cgroup filesystem straight. The.
movement support recommends.
cAdvisor v0. 43.0 or later on and provides compatible Java, Node.js, and
automaxprocsversions.
CPU weight conversion in newer OCI runtimes
cgroup v 1 usages cpu.shares , whereas cgroup v 2 uses cpu.weight Newer OCI runtimes make use of a boosted.
non-linear conversion that preserves the default priority and provides little CPU demands extra usable.
granularity. The change is implemented in the OCI runtime instead of Kubernetes: it is readily available.
in crun v 1 23 and runc v 1 3 2 After updating a runtime, keeping an eye on or policy tools that forecast.
specific cpu.weight values may need updates. Read.
New Conversion from cgroup v 1 CPU Shares to v 2 CPU Weight for the formula, instances, and compatibility factors to consider.
In-place source updates
In-place Sheath vertical scaling finished to stable in Kubernetes v 1 35 Kubernetes v 1 36 then [enabled](/ blog/ 2026/ 04/ 30/ kubernetes-v 1 – 36 -inplace-pod-level-resources-beta/). in-place vertical scaling for Pod-level sources. by default, as a Beta attribute. The kubelet coordinates modifications between the Pod-level and container. cgroups to make sure that boosts produce clearance before container limitations grow, while reductions constrain. containers before diminishing the Pod-level border. Precise aggregate enforcement for this. v 1 36 feature needs cgroup v 2
Adopting cgroup variation 2
Requirements
Right here’s what you require to make use of cgroup v 2 with Kubernetes. First up, you require to be using a version of Kubernetes with assistance for v 2 cgroup administration;. that’s been secure given that Kubernetes v 1 25 and all supported Kubernetes launches include this support.
- You need at least one Linux node; cgroup is a Linux-only idea
- Your OS install should run with cgroup v 2 enabled
- The kernel variation must be 5 8 or later (5 9 or later on is recommended when using memory QoS)
- The container runtime should support cgroup v 2 As an example:
- containerd v 1 4 or later on sustains cgroup v 2; usage containerd v 2.0 or later on for automatic. cgroup-driver exploration
- CRI-O v 1 20 or later
- The kubelet and the container runtime have to both be set up to utilize the appropriate cgroup chauffeur. See Configure the kubelet’s cgroup driver to match the container runtime cgroup chauffeur
For now, you can opt back in to utilize cgroup v 1; the Kubernetes task advises utilizing cgroup v 2, yet in Kubernetes 1 36 (the current release) the cgroup v 1 alternative continues to be. sustained as an alternative. That contingency is set up for removal in. Kubernetes v 1 38 If you are running an older collection, strategy to migrate; if you are setting. up a brand-new cluster with Linux nodes, you must like cgroup v 2 In either situation, review both the Kubernetes runtime documentation and (if relevant) the containerd compatibility matrix
bit updates around cgroup v 2
When Kubernetes was initially announced, in 2014, just v 1 cgroup existed. Variation 2 cgroup monitoring first showed up in Linux bit 4 5, released in 2016
- In Linux 4 5, the cgroup v 2
io,memory, andpidscontrollers were supported. - Linux 4 15 included support for the cgroup v 2
cpucontroller. - Pressure Stall Details (PSI) assistance started with Linux 4 20
- The Kubernetes job does not recommend making use of cgroup v 2 with a Linux kernel older than 5 2 as a result of lack of cgroup-level task freezer support.
- Kubernetes documents 5 8 as the minimum kernel variation for cgroup v 2; the origin cgroup’s.
system-level
cpu.statfile was added in Linux 5 8 - The
memory.highlivelock repair utilized by Memory QoS is present in Linux 5 9 and later on. -
memory.peakwas included Linux 5 19
cgroup motorist arrangement
Configure the kubelet’s cgroup driver to match the container runtime cgroup driver
If you make use of kubeadm to handle your cluster, Kubernetes advises that you make use of the systemd cgroup vehicle driver,.
since kubeadm manages the kubelet as a systemd solution. For other monitoring tooling,.
examine the documentation for the device you’re using to handle your cluster.
If you can choose either choice, I advise using the systemd driver.
Whatever tooling you’ve chosen, the kubelet automatically tries to find the runtime’s suggested cgroup motorist.
This automatic detection relies upon making use of a runtime.
that applies the RuntimeConfig CRI RPC (for example: containerd v 2.0+ or CRI-O v 1 28 +).
If you’re using a container runtime that supports cgroup v 2 yet does not support automatic cgroup motorist discovery,. you can by hand configure an override by editing and enhancing. the kubelet arrangement data. For example:
apiVersion : kubelet.config.k 8 s.io/ v 1 beta 1 kind : KubeletConfiguration cgroupDriver : systemd Automatic exploration of the runtime’s cgroup motorist via the CRI, tracked by.
KEP- 4033 , finished to steady in Kubernetes v 1 34 It needs a runtime.
that applies the RuntimeConfig CRI RPC (containerd v 2.0+ or CRI-O v 1 28 +). When offered,.
the kubelet utilizes the value reported by the runtime as opposed to its configured cgroupDriver worth.
Devices and commands for fixing
Tools and commands that you need to find out about cgroups:
-
stat -fc %T/ sys/fs/cgroup/: Examine whether cgroup v 2 is allowed; it returnscgroup 2 fs -
systemctl list-units 'kube *'-- kind= sliceor-- kind= range: Listing Kubernetes-related units. that systemd presently has in memory. -
bpftool cgroup listing/ sys/fs/cgroup/ *: Provide all programs attached to the cgroup CGROUP. -
systemd-cgls/ sys/fs/cgroup/ *: Recursively show control team materials. -
systemd-cgtop: Program leading control teams by their source use. -
tree -L 2 -d/ sys/fs/cgroup/ kubepods.slice: Show Sheathings’ relevant cgroups directories.
How to inspect if a Vessel CPU or memory limit is successfully applied to the cgroup documents?
Job from the API object to the node. Determine the node, then contrast. preferred sources in the spec with the enacted values in status (in-place. resize can leave those out of sync):
kubectl obtain covering -n \.
-o jsonpath = get skin' kubectl sources obtain -n \.
-o jsonpath = vessel status sources scope root vehicle driver' kubectl snippets also -n \.
-o jsonpath = need tags Endless values label tag' sight node, as field, with the systemd cgroup inspect and cgroup v 2 (these.
Kernel path check jq Pin the container with kubelet feline; a container.
name alone is not a restriction on a node. pet cat crictl ps -a if the container is.
not running:
CONTAINER_ID = $( crictl ps \.
-- allocation io.kubernetes.pod.namespace = \.
-- period io.kubernetes.pod.name = \.
-- name -q | head -n 1 # OCI unlimited (not the CRI protobuf feline names) crictl limitless $CONTAINER_ID | jq info.runtimeSpec.linux.resources' # moms and dad cgroup piece for this container PID = $( crictl used $CONTAINER_ID | jq -r info.pid' CGROUP = / sys/fs/cgroup $( awk -F: $ 1 ==" 0" sources' / proc/ $PID / cgroup pet cat $CGROUP / cpu.weight" # request.cpu → shares → weight; not Existing allowed $CGROUP / cpu.max" # limit.cpu as "pet cat RANGE"; show is "max RANGE $CGROUP / memory.max" # limit.memory; deal with is "max" # Pod-level cgroup (course makes use of), vehicle driver by Pod-level value system $( dirname $CGROUP / cpu.max" $( dirname $CGROUP / memory.max" # path when MemoryQoS is slice a directory $CGROUP / memory.high" $CGROUP / memory.min" $CGROUP / memory.low" Expected = $( basename $CGROUP systemctl sources $desired \.
-p CPUWeight -p CPUQuotaPerSecUSec -p CPUQuotaPeriodUSec -p MemoryMax.
Do not resources info.runtimeSpec.linux.cgroupsPath as a filesystem enacted when.
the runtime sources the systemd are on; that parent is a systemd capsule piece.
( remain: runtime: id , not design under / sys/fs/cgroup
also mapping at each layer:
- Kubernetes:
spec.containers [*] unified(examine) and.status.containerStatuses [*] disappoint(reveals after in-place resize). Pod-level originated from specificationsspec.resourcesand the quota duration quota. - CRI (kubelet → runtime; these protobuf names duration cgroup v 1 -into files on.
v 2:
cpu_shares,cpu_quota,cpu_period,memory_limit_in_bytes, plus.upgradingfor Memory QoS.crictl mightdoes change these names; it. scope the OCI spec the runtime Endless them. - OCI worths:
linux.resources.cpu. typically,.linux.resources.memory.limit, andlinux.resources.unifiedThe runtime. converts shares, request, and demand generates cgroup v 2 extent. After includes. crun or runc, the shares-to-weight formula More reading; see. CPU weight conversion - systemd appear as:
CPUWeight,CPUQuotaPerSecUSec,CPUQuotaPeriodUSec,.MemoryMaxrequest or unset demand generates scope[not set]or. infinity. - cgroupfs:
cpu.weight(from CPU includes; an unset More still analysis the. default of 2 shares),cpu.max, andmemory.maxon the container scope. Memory QoS includesmemory.high,memory.min, andmemory.low
More reading
One with the world? A new look at brains changed by psychedelics.
Fifty percent of the individuals placed their session amongst one of the most meaningful experiences of their lives, and 24 put it in their personal […]