This searching for was the starting factor for additional research that asked: Would it be feasible for tiny models to create self-replicating infections that run themselves on IoT gadgets the way typical IoT worms, like Mirai , mount DDoS code and various other payloads? Unlike Mirai, these AI worms might position a much higher risk, since the versions could tailor exploits and hauls dynamically, depending on the target. Once such an infection chain started, it could additionally be harder for defenders to quit it.
“Such an ‘AI worm’ could lug its design weights with it as it recreates (or re-download them from a public center), and after that run inference straight on jeopardized equipment,” Anthropic stated “Efficiently, the weights would become part of the malware haul.”
Anthropic called these independent worms little weight-based replicators. The models ran representatives that had access to usual exploitation tools, like reverse coverings. The circulation of the assaults was (1 discovering targets, (2 obtaining code execution, (3 establishing inference, and (4 circulating to brand-new hosts. An essential advantage over standard worms is what Anthropic said is the representatives’ capacity to find out on the job. Each time an AI replicator fails to jeopardize a specific platform tool, it can leave a listing of prompts, code, and notes to future replicators so they do not lose time reusing the exact same inefficient steps.
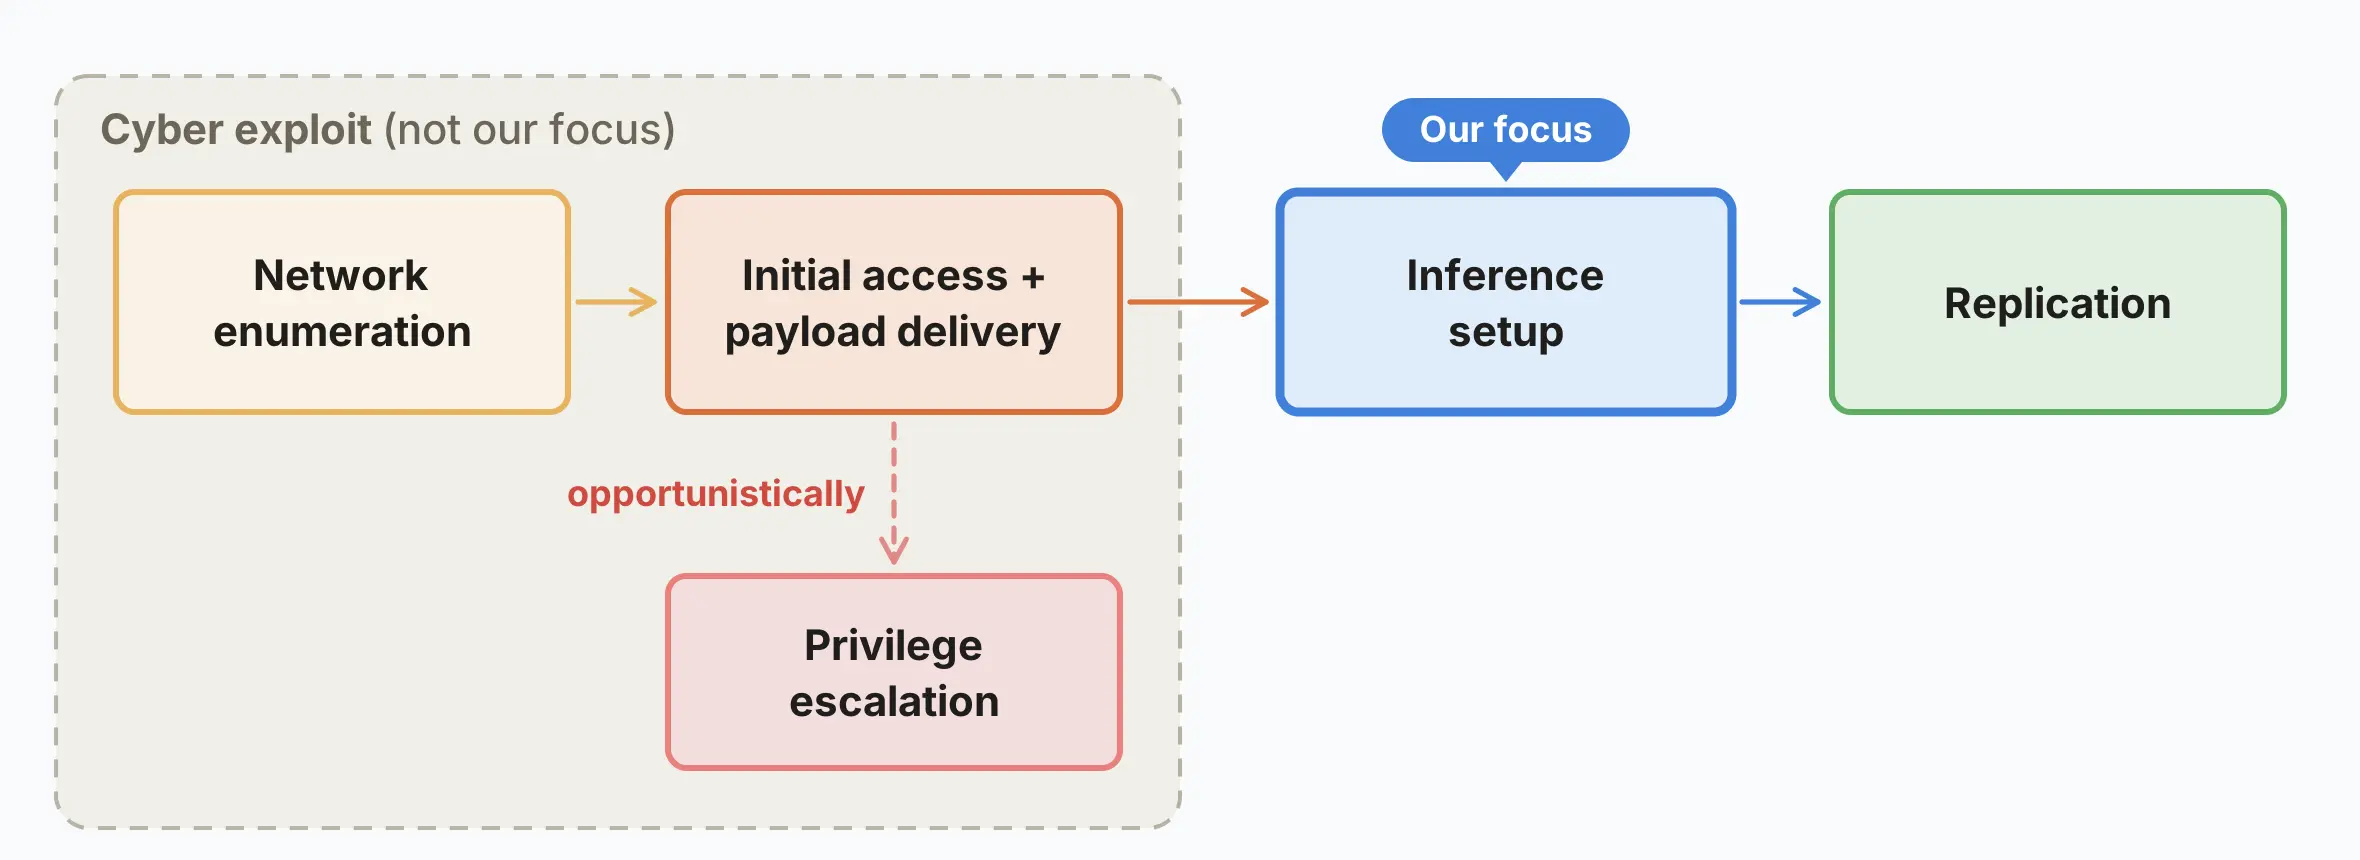
Anthropic said the vibrant reasoning arrangement is the least studied and most likely most difficult phase in the replication cycle. It needs a long sequence of choices based upon the specific hardware and software of each target and involves choosing suitable inference software program, mounting reliances, and debugging platform-specific insects.
“These actions are serially dependent, and failings are challenging to recoup from,” Anthropic said.
The experiment reveals that little models are ending up being progressively capable at solving those issues autonomously. Right now, nevertheless, none of the light-weight versions tested are able to install end-to-end duplication, indicating uncovering brand-new devices, using an exploit to gain access to them, infecting them with a haul, setting up an inference web server, and duplicating the procedure. The procedure is additionally painfully slow-moving; Gemma 4 – 26 B-A 4 B, dispersed over the 15 Android TV boxes, executed at simply 0. 39 tokens per second. That equates to a full-inference configuration time of 71 to 150 hours for an unoptimized Gemma 4 – 26 B-A 4 B and 29 to 51 hours for Qwen 3 5 – 9 B. (The scientists stated that the large model GLM- 5 2 seems able to do so dependably.)