I assumed it would be fun to examine a variety of open source LLMs on actual client job using Codex cli.
I developed a benchmark test based upon genuine customer requests in existing codebases, after that arranged the tasks from simplest to hardest.
The results were unexpected. I found that coding benchmarks don’t always line up with my actual job. The smarter designs typically got lost in a train of thought and didn’t in fact edit the files.
A version that can address a standalone shows problem is not always beneficial when the task is “repair this little customer concern in a five-year-old WordPress theme without making a mess.”
If you plan to do a similar test utilizing Codex cli and DeepInfra, you may require a shim to connect both.
Summary of Outcomes
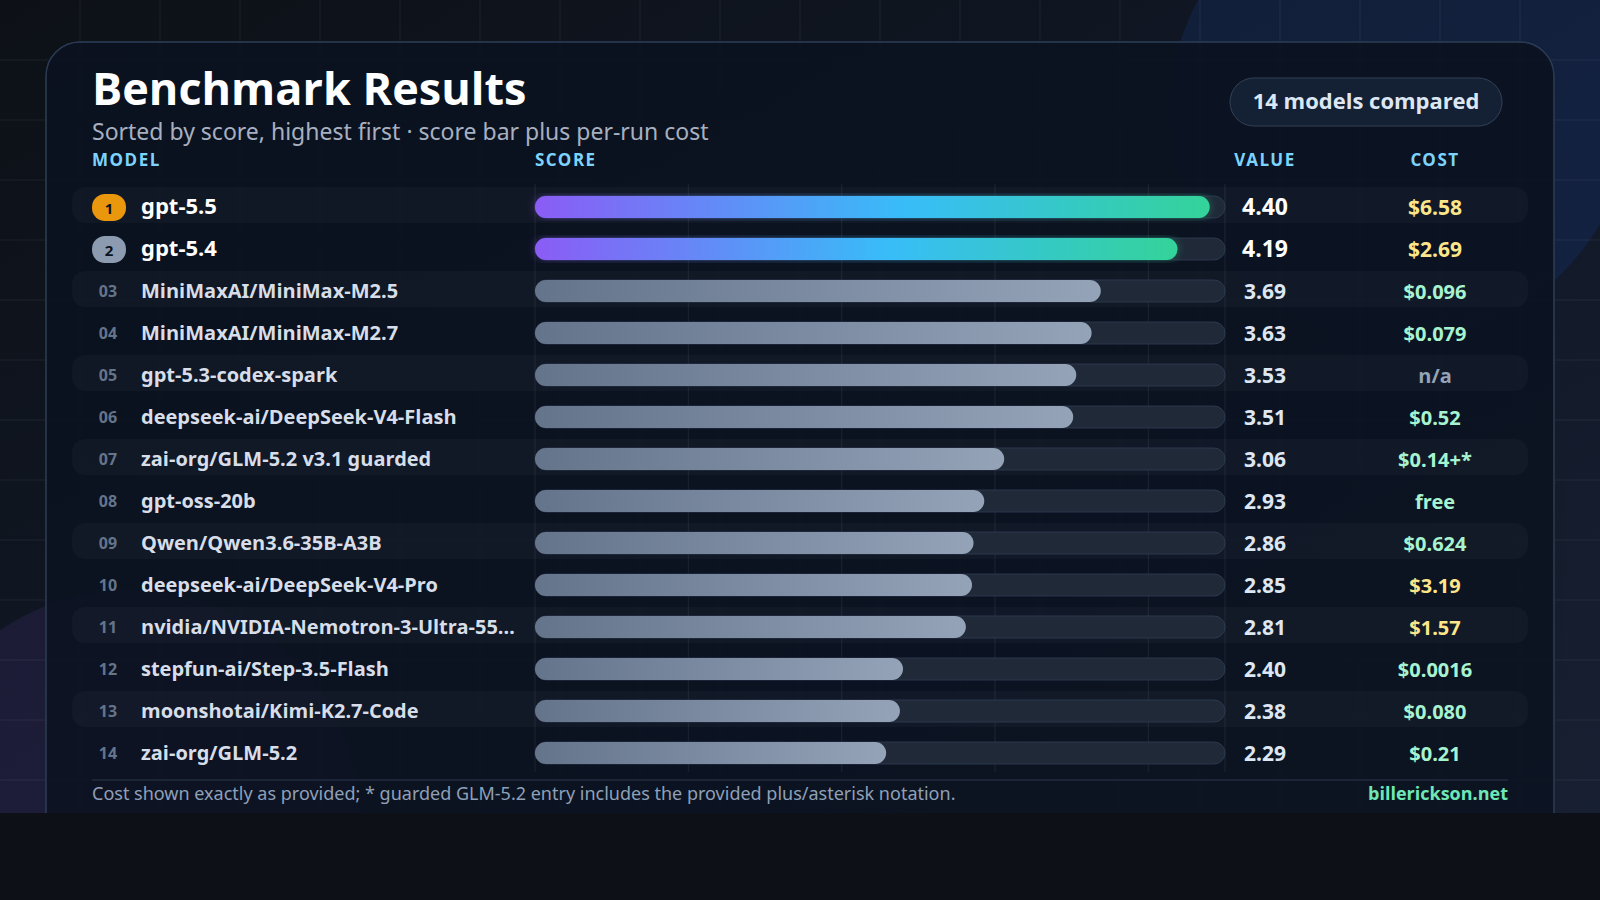
The top OpenAI versions won on top quality. That was not unusual. I’m sure the Anthropic models would additionally be in the direction of the top, yet I intended to contrast my day-to-day driver (gpt- 5 5 to open up source designs.
MiniMax was the greatest price/performance shock, which led me to do a second benchmark test contrasting simply those 2 versions.
GLM- 5 2’s bad efficiency was likewise unforeseen. You can see the Test Information listed below for even more details on its run.
The “price” column reveals the real cost of running this test on DeepInfra based upon the token use. The OpenAI prices are based on their API rates, but I get on among their paid plans which drastically subsidizes token use.
I made use of a free regional model (gpt-oss- 20 b) as a baseline standard, and didn’t anticipate it to rack up in the middle of the pack on these jobs.
MiniMax Examination
Offered the unusual outcomes for the MiniMax models, and how close their scores were in the initial examination, I created a brand-new benchmark examination with six brand-new tasks simply to check those 2 models. All these jobs were medium-to-hard, so the scores are lower.
MiniMax-M 2 7 balanced 2 63 across the 6 jobs and spent $0. 146 It was less costly on symbols, however it stopped working 3 accuracy jobs terribly.
MiniMax-M 2 5 balanced 3 53 throughout the 6 tasks and invest $0. 150 It was somewhat more expensive, however materially a lot more reputable on PHP/WordPress tasks.
Recap: I’m mosting likely to keep using gpt- 5 5 as my primary model, however I may attempt using MiniMax-M 2 5 for simpler jobs.
Examination Details
This criteria evaluated coding-agent habits across 4 WordPress style jobs utilizing short, all-natural triggers while beginning Codex in the correct motif directory site with the CultivateWP typical profile energetic. Task 1 was a read-only brand-color lookup, Job 2 was a mechanical migration of customized ACF block shows up from apiVersion 2 to 3, Task 3 was a focused footer email/form web link styling solution, and Job 4 was a wider post-header application. Ratings are out of 5 per job, with the typical reflecting the four-task run where available.
The clearest pattern was that lookup and mechanical edits were much easier than design-aware implementation. Numerous designs could discover ‘theme.json’ or update 23 ‘block.json’ documents easily, but had a hard time as soon as the job required selecting the appropriate SCSS/PHP source target, preserving build parity, and quiting with a tiny reviewable diff.
zai-org/GLM- 5 2
GLM- 5 2 balanced 2 29 at an approximated expense of $0. 21 It dealt with the brand-color lookup well after the benchmark metadata concern was fixed, however the implementation jobs revealed a relentless stall pattern. Job 2 produced some tidy, slim manifest edits however did not end up the complete collection, and Tasks 3 and 4 ended without purposeful application prior to operator caps.
The outcome was a model that can understand the repo and identify relevant locations, however did not reliably cross from examination right into finished modifications. In this benchmark, that made it weak as a hands-off coding representative in spite of a strong read-only job outcome.
After the first poor results, we made some process modifications and re-ran the test, which you’ll find below in zai-org/GLM- 5 2 v 3 1 safeguarded
moonshotai/Kimi-K 2 7 -Code
Kimi-K 2 7 -Code balanced 2 38 at an estimated cost of $0. 080 It addressed the brand-color lookup accurately, yet was slow for such a straightforward read-only task and did extra searching after finding the authoritative file. On the coding jobs, it consistently found the right data or target collections, after that stalled without creating a functional diff prior to caps were reached.
This made Kimi among the more irritating runs: the exploration commonly looked encouraging, yet the final worktree did not mirror that understanding. Its low estimated cost assists, yet the absence of finished edits on Tasks 2 – 4 makes it tough to trust for ignored execution.
stepfun-ai/Step- 3 5 -Flash
Action- 3 5 -Flash balanced 2 40 , with expense taped as at least $0. 0016 because some disturbed jobs did not produce last use. It was quick and accurate on the brand-color lookup, yet Job 2 showed serious scope-control problems. Although it transformed the API version, it likewise eliminated acf.mode , added customClassName extensively, reformatted files, and maintained wandering after the beneficial part of the edit was done.
Task 3 located handy context but created no diff, and Job 4 was avoided after the lowered job set showed below-threshold execution habits. The small cost is intriguing, however the edits were not reviewable sufficient for real manufacturing use.
nvidia/NVIDIA-Nemotron- 3 -Ultra- 550 B-A 55 B
Nemotron Ultra averaged 2 81 at an approximated expense of $ 1 57 It succeeded on the very first 2 jobs: the lookup was precise, and the ACF block API migration generated a strong last diff. Nonetheless, those success featured high token usage and some malformed validation commands on the mechanical edit.
The application side was the issue. Job 3 did not land a resource repair and left a back-up artifact. Task 4 was missed for budget security, so the overall result was a solid begin complied with by a costly application failing.
deepseek-ai/DeepSeek-V 4 -Pro
DeepSeek-V 4 -Pro averaged 2 85 at an approximated cost of $ 3 19 Its very first two tasks were excellent from a final-diff viewpoint: precise lookup, tidy mechanical show updates, and excellent validation shape. The drawback was effectiveness, particularly Task 2, which took around 4 mins and virtually 0. 9 M input tokens for an uncomplicated file-wide version bump.
Task 3 ran for more than 11 mins without producing a diff, and Job 4 was not run. The design appeared to be thinking toward a probable resource target, but also for this benchmark the scored deliverable was the ended up worktree, not the direction of traveling. The cost-to-output proportion was poor.
Qwen/Qwen 3 6 – 35 B-A 3 B
Qwen 3 6 – 35 B-A 3 B balanced 2 86 at an estimated cost of $0. 624 It finished the lookup properly and did materialize edits on Jobs 2 and 3, however those edits were not specifically disciplined. Job 2 ended up the migration however introduced unneeded support and context adjustments, making the diff riskier than the clean one-line show updates from stronger runs.
Task 3 generated a probable regional CSS adjustment, yet likely targeted the narrower block CSS path as opposed to the designated footer type result. It additionally burned greater than 2 M input tokens on that scoped styling task. Task 4 was effectively a no-op on the real worktree, which maintained the total rating listed below the more powerful partial implementers.
gpt-oss- 20 b
The local gpt-oss- 20 b balanced 2 93 and was cost-free to run in your area. It stayed a useful baseline: exact on the brand-color lookup, clean on the mechanical block.json movement, and far better behaved than several paid organized designs on artifact hygiene. It avoided back-up files and did not dispose compiled CSS during the footer exploration.
Its weak point was implementation follow-through. Job 3 recognized relevant block data yet never edited CSS or SCSS, and Task 4 returned virtually promptly without any beneficial job. The design was affordable and tidy, however not capable enough for both sensible coding jobs in this standard.
zai-org/GLM- 5 2 v 3 1 guarded
The secured GLM- 5 2 rerun averaged 3 06 , with expense videotaped as a minimum of $0. 14 The neutral guardrail materially improved the mechanical ACF block job: Job 2 went from incomplete in the original GLM run to a tidy, right movement. That recommends GLM’s failings were partially sensitive to job framing and agent-loop behavior, not just inability to understand the repo.
The guardrail did not deal with broader implementation dependability. Tasks 3 and 4 still shed time on inspection and finished without beneficial diffs prior to driver caps. It was a meaningful improvement over the original GLM run, yet insufficient to make it affordable with the better execution performers.
deepseek-ai/DeepSeek-V 4 -Flash
DeepSeek-V 4 -Flash balanced 3 51 at an approximated cost of $0. 52 It was strong on the lookup and mechanical API migration, creating scoped, legitimate modifications. Compared with V 4 -Pro, it was cheaper and eventually better in this criteria due to the fact that it completed all four tasks and produced genuine application diffs.
The application top quality was still just partial. Task 3 was syntactically tidy however likely missed the desired footer form link target, and included a high-risk truncate-and-recover episode. Task 4 freshened noticeable post-header designing with source and put together CSS, however missed much deeper theme and recipe-card compatibility actions anticipated by the golden course.
gpt- 5 3 -codex-spark
gpt- 5 3 -codex-spark balanced 3 53 ; cost was marked n/a since no main API cost was available. It executed well on the lookup and mechanical reveal update, with a clean last diff on Job 2 in spite of some failed covering attempts and an imprecise last documents matter. As with numerous versions, the basic jobs were much stronger than the application tasks.
Job 3 tried the right area but created fragile styling job: misshaped source SCSS, hand-appended assembled CSS, and a web link shade that likely fell short the readability objective in the dark footer. Job 4 created valid PHP and some beneficial conditional behavior, yet skipped resource SCSS and wider recipe-template compatibility. It was an actual coding run, just not a tidy one.
MiniMaxAI/MiniMax-M 2 7
MiniMax-M 2 7 balanced 3 63 at an approximated cost of $0. 079 It was among the strongest price/performance results in the benchmark. The lookup was exact and extremely quick, and Job 2 created a right last movement with tidy validation, though it at first missed out on the embedded reveal prior to recuperating.
The execution jobs were genuine however partial. Job 3 made a plausible regional block CSS repair, however possibly missed the actual footer type course. Job 4 enhanced PHP structure and resource SCSS much more easily than M 2 5, yet did not update put together CSS or attend to the more comprehensive WPRM/template compatibility anticipated by the reference execution. For the expense, it went over; for manufacturing use, it still required mindful evaluation.
MiniMaxAI/MiniMax-M 2 5
MiniMax-M 2 5 averaged 3 69 at an estimated price of $0. 096 It was the largest pleasant shock of the DeepInfra set. The design was precise on the lookup, generated an exactly proper API-version diff on Job 2, and normally supplied valuable edits at affordable.
Its weak side was implementation precision. Task 3 generated a diff instead of stalling, yet likely targeted the wrong footer kind resource course and discarded a large put together CSS documents right into the records. Job 4 touched PHP, source SCSS, and compiled CSS, but missed significant golden-path habits around metadata helpers and WPRM recipe-template compatibility, and recognition left some artifact issues.
gpt- 5 4
GPT- 5 4 averaged 4 19 at an estimated price of $ 2 69 It was solid throughout the initial two jobs, consisting of a sourced brand-color solution and a precise, well-scoped ACF block API modify. It spent even more symbols than needed on the simple migration, yet the last job was correct and reviewable.
Its execution jobs were meaningfully much better than the open-model area, though still not best. Job 3 likely taken care of the front-end readability problem, yet did so with a brand-new enqueued stylesheet and more comprehensive WPForms targeting than the recommendation. Job 4 provided legitimate PHP and runtime CSS, yet missed out on several gold touch points.
gpt- 5 5
GPT- 5 5 was the top entertainer, balancing 4 40 at an approximated expense of $ 6 58 It was precise and well sourced on the lookup, produced the anticipated tracked diff for the ACF block API movement, and stayed clear of backup artifacts. It was not perfectly efficient, but the final results were constantly better than the remainder of the field.
The most crucial distinction was that GPT- 5 5 generated the toughest implementation results. Task 3 was useful, scoped, accessibility-conscious, and kept resource SCSS and compiled CSS in sync. Job 4 was a genuine hard-task application with concentrated files, tidy PHP syntax, compiled front-end CSS, and sensible use of existing helpers. It still missed components of the historical golden direction, yet it was the very best functional coding-agent result in the standard.